The right model for every request.
AVELIN's own trained decision model reads each request and picks the model it needs: a more capable one for hard tasks, a cheaper one for easy ones. It works with the providers you already use. Run it in our cloud, on your own GPUs, or both.
Up to 90% lower cost per task. In our live Arena, at list prices. See it in the Arena
- Decision Layer
- Picks the model for each request. Starts with a POC on the providers you already use.
- Sovereign platform
- Nine AVELIN models and an API platform, on your own GPUs.
A deep-tech team that researches, trains and evaluates models, and builds the product. Meet the team
Four problems enterprises hit with AI.
Enterprises are moving AI agents into production. Four problems follow.
$50
per 1M output tokens. Top models list at up to this price.
Top models are priced for the hardest work.
AI agents do not answer once and stop. They loop, call tools and retry, so one task can use about 4 to 15 times the tokens of a chat.
The Decision Layer picks the model for each request. Decision Layer
Vendor list prices, read 24 Sep 2026. Token multiples: Anthropic, 13 Jun 2025.
54%
of AI requests went to a more expensive model than the task needed.
Most tasks do not need the top model.
In the same research, 90% of more than 9,000 tasks did not need a top model. Teams still send everything there, to be safe.
The Decision Layer picks the level each request needs. Hard tasks still go to a top model. How it picks
Accenture, The CIO's Guide to AI Tokenomics, 10 Sep 2026. 750 senior executives, 17 countries.
79%
of finance leaders reported AI cost overruns in the past 12 months.
Budgets overrun, and cost is not tied to a task.
A bill by provider does not show which team, agent or task caused it. Only 35% of companies can calculate the cost per business outcome of their largest AI use case.
AVELIN shows cost by team, key and model, with budgets and caps. API platform
DoiT, survey by Sapio Research, Feb 2026: 500 finance leaders, US and UK. Accenture, 10 Sep 2026.
76%
of 750 IT, security and AI leaders were highly or extremely concerned about data security and privacy. It ranked first among the AI concerns listed.
Privacy is the top-ranked AI worry.
The question is not only who can read a prompt. It is where the prompt runs, how long it is kept, and whether it can leave. A ban does not remove that risk. Control does.
AVELIN gives you three levels of control. Privacy
AvePoint, State of AI 2026, research by Osterman. AvePoint sells data-governance software.
Nobody risks a cheaper model. The workflow could break. So the top model stays the default. The Decision Layer reads each request and makes that choice for you.
The Decision Layer chooses the model for each request.
AVELIN's own trained decision model reads each request and picks the model it needs: a more capable model when the task needs intelligence, a cheaper one when it is easy, on every request.
Read.
The decision model works out what kind of job a request is and how hard it is.
Choose.
It sends the request to the level of model that fits. A hard task goes to a capable model. An easy one goes to a cheaper one.
Record.
Every decision is logged with its reason, so you can see what each request cost and why.
Up to 90% lower cost per task.
In our live Arena, at list prices.
90.1%
median cost cut per task
76.6%
all runs added up
94.4%
75th percentile
99.4%
best run
The Arena is a public demo with its own privacy page, so do not paste confidential data into it.
The Arena measures the Decision Layer at list prices, cost only. Self-hosted deployments can be cheaper still: no per-token bill, and marginal cost is your own hardware.
Works with the providers you already use.
Connect your own accounts with OpenAI, Google Gemini, Anthropic, DigitalOcean, ElevenLabs and other providers. The Decision Layer chooses among them, AVELIN models and models on your own GPUs.
What else it does.
Self-learning loop
You switch it on or off. When it is on, AVELIN distills your data to improve quality, cut cost and speed up work.
Quality analysis
Answers are scored, so you can see whether a cheaper model held up.
Dangerous-request detection
Spots dangerous requests before they reach a model.
Private-data detection
Spots private data in a request. In a hybrid deployment, it feeds the privacy check.
Tuned for each enterprise
The Decision Layer is tuned to each enterprise's tasks and rules.
A POC is a proof of concept on one of your workloads. You get a cost-per-task report next to your current setup.
A sovereign AI platform on your GPUs.
AVELIN's inference layer installs on your GPUs and is optimized for them at GPU level. It runs nine AVELIN models, each fine-tuned for one kind of work, with an API platform on top. You decide where the system runs and who can reach it.
Inference layer.
Installs on your GPUs and is tuned at GPU level for efficient token generation.
3 families · 9 models.
Chat for knowledge, images, documents and PDFs. Coding for math and code, with large context. Agents for 24/7 volume work, built for speed and price. Each family has fast, pro and ultra tiers, and all nine are tuned to work with the Decision Layer.
API platform.
OpenAI-compatible and Anthropic-compatible, with speech-to-text, text-to-speech, web search and web scraping. Observability and cost control by team, key and model. User management.
Your workflows.
The models can be fine-tuned or trained on your own workflows.
The nine models at a glance
| Family | fastSpeed and low cost. | proBalanced, for medium complexity. | ultraThe hardest tasks, where intelligence matters. |
|---|---|---|---|
| ChatKnowledge work. Mostly multimodal: images, documents and PDFs.256K context | avelin-fast | avelin-pro | avelin-ultra |
| CodingMath and code. Large context windows for the most complex tasks.1M context | avelin-coding-fast | avelin-coding-pro | avelin-coding-ultra |
| AgentsVolume work that runs 24/7, built for speed and price. Handles complex tasks, including coding, with a smaller context.256K context | avelin-agentic-fast | avelin-agentic-pro | avelin-agentic-ultra |
Cloud, enterprise or hybrid.
Start in the cloud, move to your own GPUs, or run both.
AVELIN Cloud
Nine models plus the Decision Layer
Global inference in the United States, Europe and MENA. Connect your own providers to the Decision Layer to lower your token spend. Isolated in-country locations are planned.
Enterprise
Your hardware, your workflows
The Decision Layer, the full platform, or both, optimized for your hardware. Models can be tuned to your workflows.
Hybrid
Local first, a public model when needed
Local GPUs run the models. A task that needs more intelligence, or a busy local model, can be offloaded to a public model. A privacy check lets you decide whether detected private data may leave.
How hybrid decides
- Local first. The Decision Layer reads each request. Your local model on your GPUs is the default.
- Offload when needed. If the task needs more intelligence, or the local model is busy, a public model becomes an option.
- Check, then send. Before anything leaves your GPUs, the privacy check looks for private data. You decide whether it may go to a public model or must stay on your GPUs.
Privacy is three questions.
What do you keep? Where does it run? Can it leave? AVELIN answers at three levels, and you choose the level for each workload.
AVELIN Cloud
Zero retention by default.
We do not keep your prompts, and they are not used to improve AVELIN. The data policy has the detail.
Hybrid
You decide what may leave.
Local models run on your GPUs. A privacy check lets you choose: detected private data may go to the cloud, or must stay on your GPUs.
On-premise
The ultimate privacy.
Prompts are processed on your own GPUs.
Optional: help us improve AVELIN. You can opt in to share anonymized requests. It is off by default, and you can switch it off at any time.
Public prices.
Pay per token, at list prices. No subscription. No minimum.
$1.14 to $12.50 per 1M output tokens
$0.285 to $2.50 per 1M input tokens
USD per 1M tokens, list prices as of 3 Oct 2026. Fast, pro or ultra: you pay for the level you use.
- Every API key can carry its own budget and rate limits. Usage and spend are live, with budget alerts.
- The Decision Layer is priced per request and quoted in a POC. Enterprise and on-premise deployments are priced by agreement.
Built by a deep-tech R&D team.
We research how to choose the right model for each request. We train and evaluate models, and we build the product around them.
The decision model.
Which model suits which request, and how to tell. We train it, and the data it learns from.
Model creation.
The nine models are each fine-tuned for one kind of work. Cross-model fusion, building the next ones from the strengths of several, is our research direction.
Inference and models.
The inference layer, optimized at GPU level, and the nine AVELIN models.
The product.
The Decision Layer, the AVELIN models and the API platform.

Yury Akinin, PhD
CEO
PhD in neural networks. Co-founded a software engineering company and directed engineering at a firm with thousands of engineers.

Dmitrii Lozhkin
Chief AI Engineer
Leads the decision-model and evaluation work.

Liudmila Prozorova, PhD, MBA
COO
Ran large procurement programmes at two energy companies and founded two ventures in the UAE.
Antonio Neri
VP Business, Europe
25 years in fintech and enterprise software.
AVELIN AI.
News.
All news- EventWeb Summit 2026: AVELIN AI Among the Conference's Startups
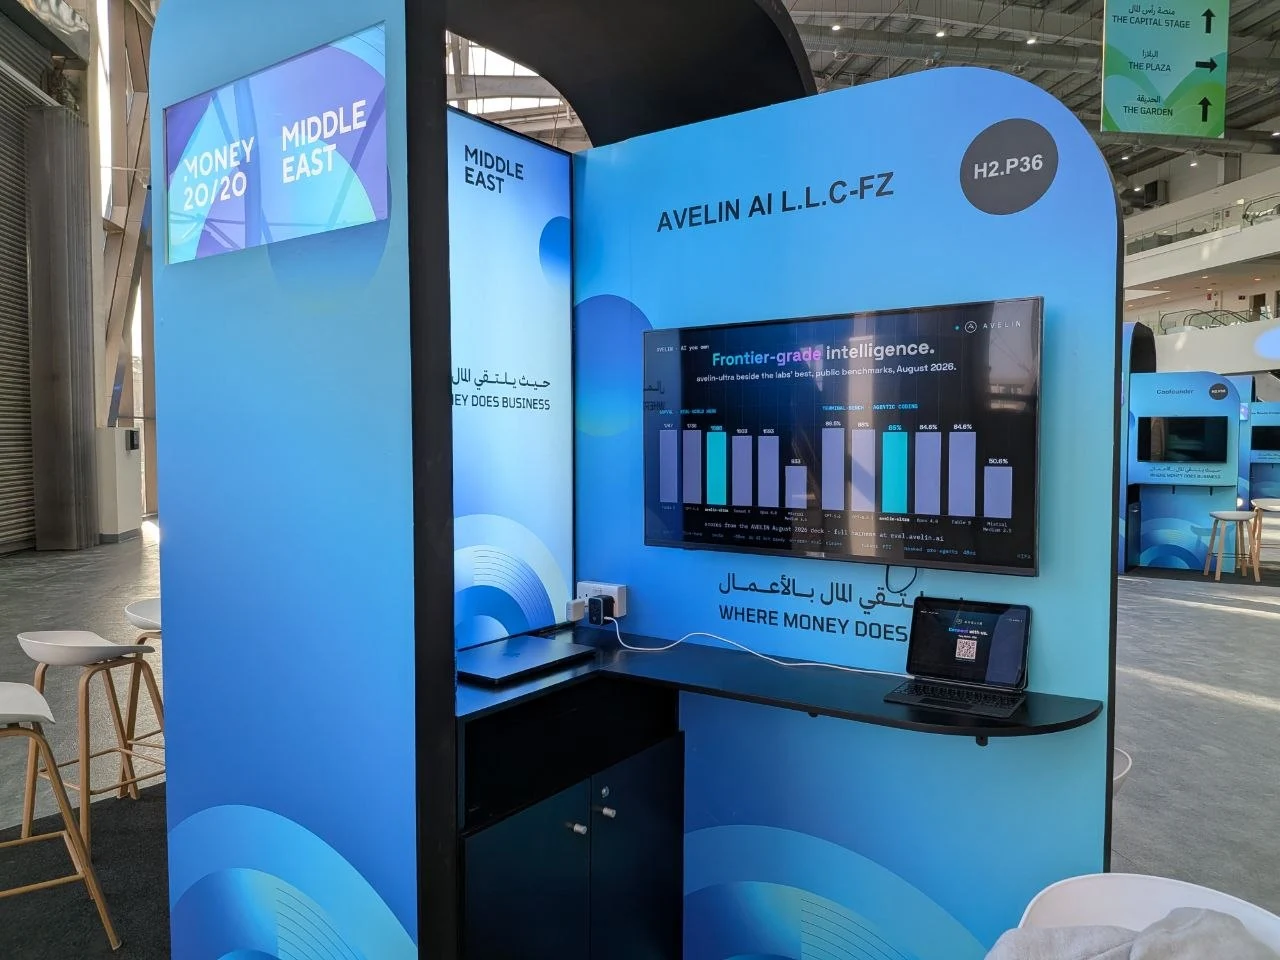
- EventSovereign AI at the Region's Top Fintech Event: AVELIN AI at Money20/20 Middle East 2026
- EventVenture Firm AltaIR Capital Accepts AVELIN AI into the AltaLab Program
- EventAVELIN AI Joins the Launchpad Program at Oraseya Capital
- RecognitionInc. Arabia Names AVELIN AI an AI Leader of Tomorrow at Its Dubai 2026 Awards
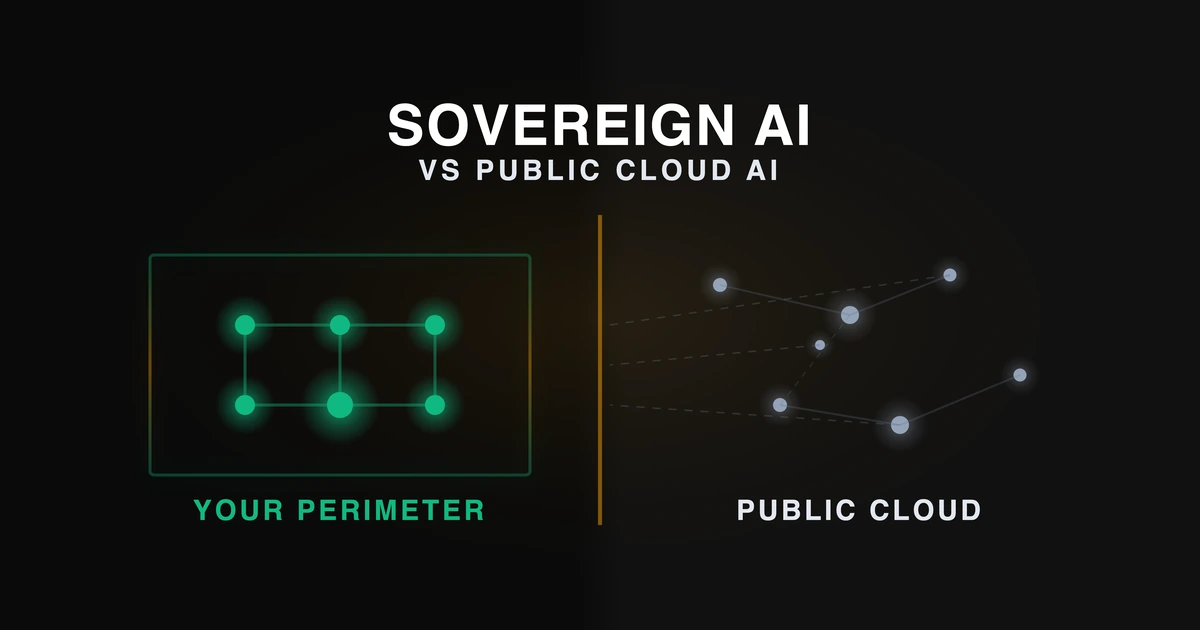
- ResearchWhat is Sovereign AI?
Frequently asked questions.
What is AVELIN?
AVELIN is a deep-tech AI company with two products. The Decision Layer picks the right AI model for every request, and the sovereign AVELIN platform runs nine AVELIN models and an API platform on your own GPUs. AVELIN Cloud gives you the models and the Decision Layer without any hardware.
What is the Decision Layer?
AVELIN's own trained decision model reads each request and picks the model it needs: a more capable model when the task needs intelligence, a cheaper one when it is easy, on every request.
How much can AVELIN cut the cost per task?
Up to 90%. In our live Arena, at list prices. Easy tasks go to a cheaper model, so the bill for the same work falls. How the figure is counted is on the Method page.
Does AVELIN work with our AI providers?
Yes. The Decision Layer works with almost any endpoint and with your own accounts at OpenAI, Google Gemini, Anthropic, DigitalOcean, ElevenLabs and other providers. It can also choose AVELIN models and models on your own GPUs.
What is a sovereign AI platform?
It means you, not a vendor or a cloud, decide where the AI system runs and who can reach it. The sovereign AVELIN platform installs AVELIN's inference layer on your own GPUs, optimized at GPU level, and runs the nine AVELIN models and an API platform there.
Do you keep my prompts?
In AVELIN Cloud, zero retention is the default, and your prompts are not used to improve AVELIN unless you opt in. On your own GPUs, prompts are processed on your hardware.
What are the nine AVELIN models?
3 families · 9 models. Chat is for knowledge, images and documents, Coding is for math and code with large context windows, and Agents is for volume work that runs 24/7. Each family has three tiers: fast for speed and low cost, pro for balanced work, and ultra for the hardest tasks.
How do we start?
Click Request a POC and tell us about one workload. We reply by email with a one-page scope. You can also try the live demo or start building with the API.
Bring one workload. See its cost per task.
POC on one workload
Tell us about one workload in the form. We reply by email with a one-page scope.
See it work
Run a task on a flagship model and on AVELIN in the Arena, and compare the two bills.
Build with it
One API, OpenAI-compatible and Anthropic-compatible. Change the base URL to start. Public list prices.